This article explains how to install ORCA (Optical Reasoning and Cognition Agent) VLM base models.
For information about the capabilities of ORCA VLMs, see our ORCA (Optical Reasoning and Cognition Agent) VLMs article.
Prerequisites
To successfully use ORCA VLMs:
Configure your infrastructure for ORCA VLMs
Make sure your instance supports GPU-enabled application machines.
On-premise deployment: follow the instructions in the “Enabling Application Machines with GPUs” article for Docker, Podman, or Kubernetes.
SaaS deployment: contact your Hyperscience representative to enable GPU support in your instance.
Learn more about Hyperscience’s GPU requirements in Infrastructure Requirements.
Learn how to install ORCA VLM base models in both internet-connected and air-gapped deployments in the sections below.
Installing an ORCA base model in deployments with internet access
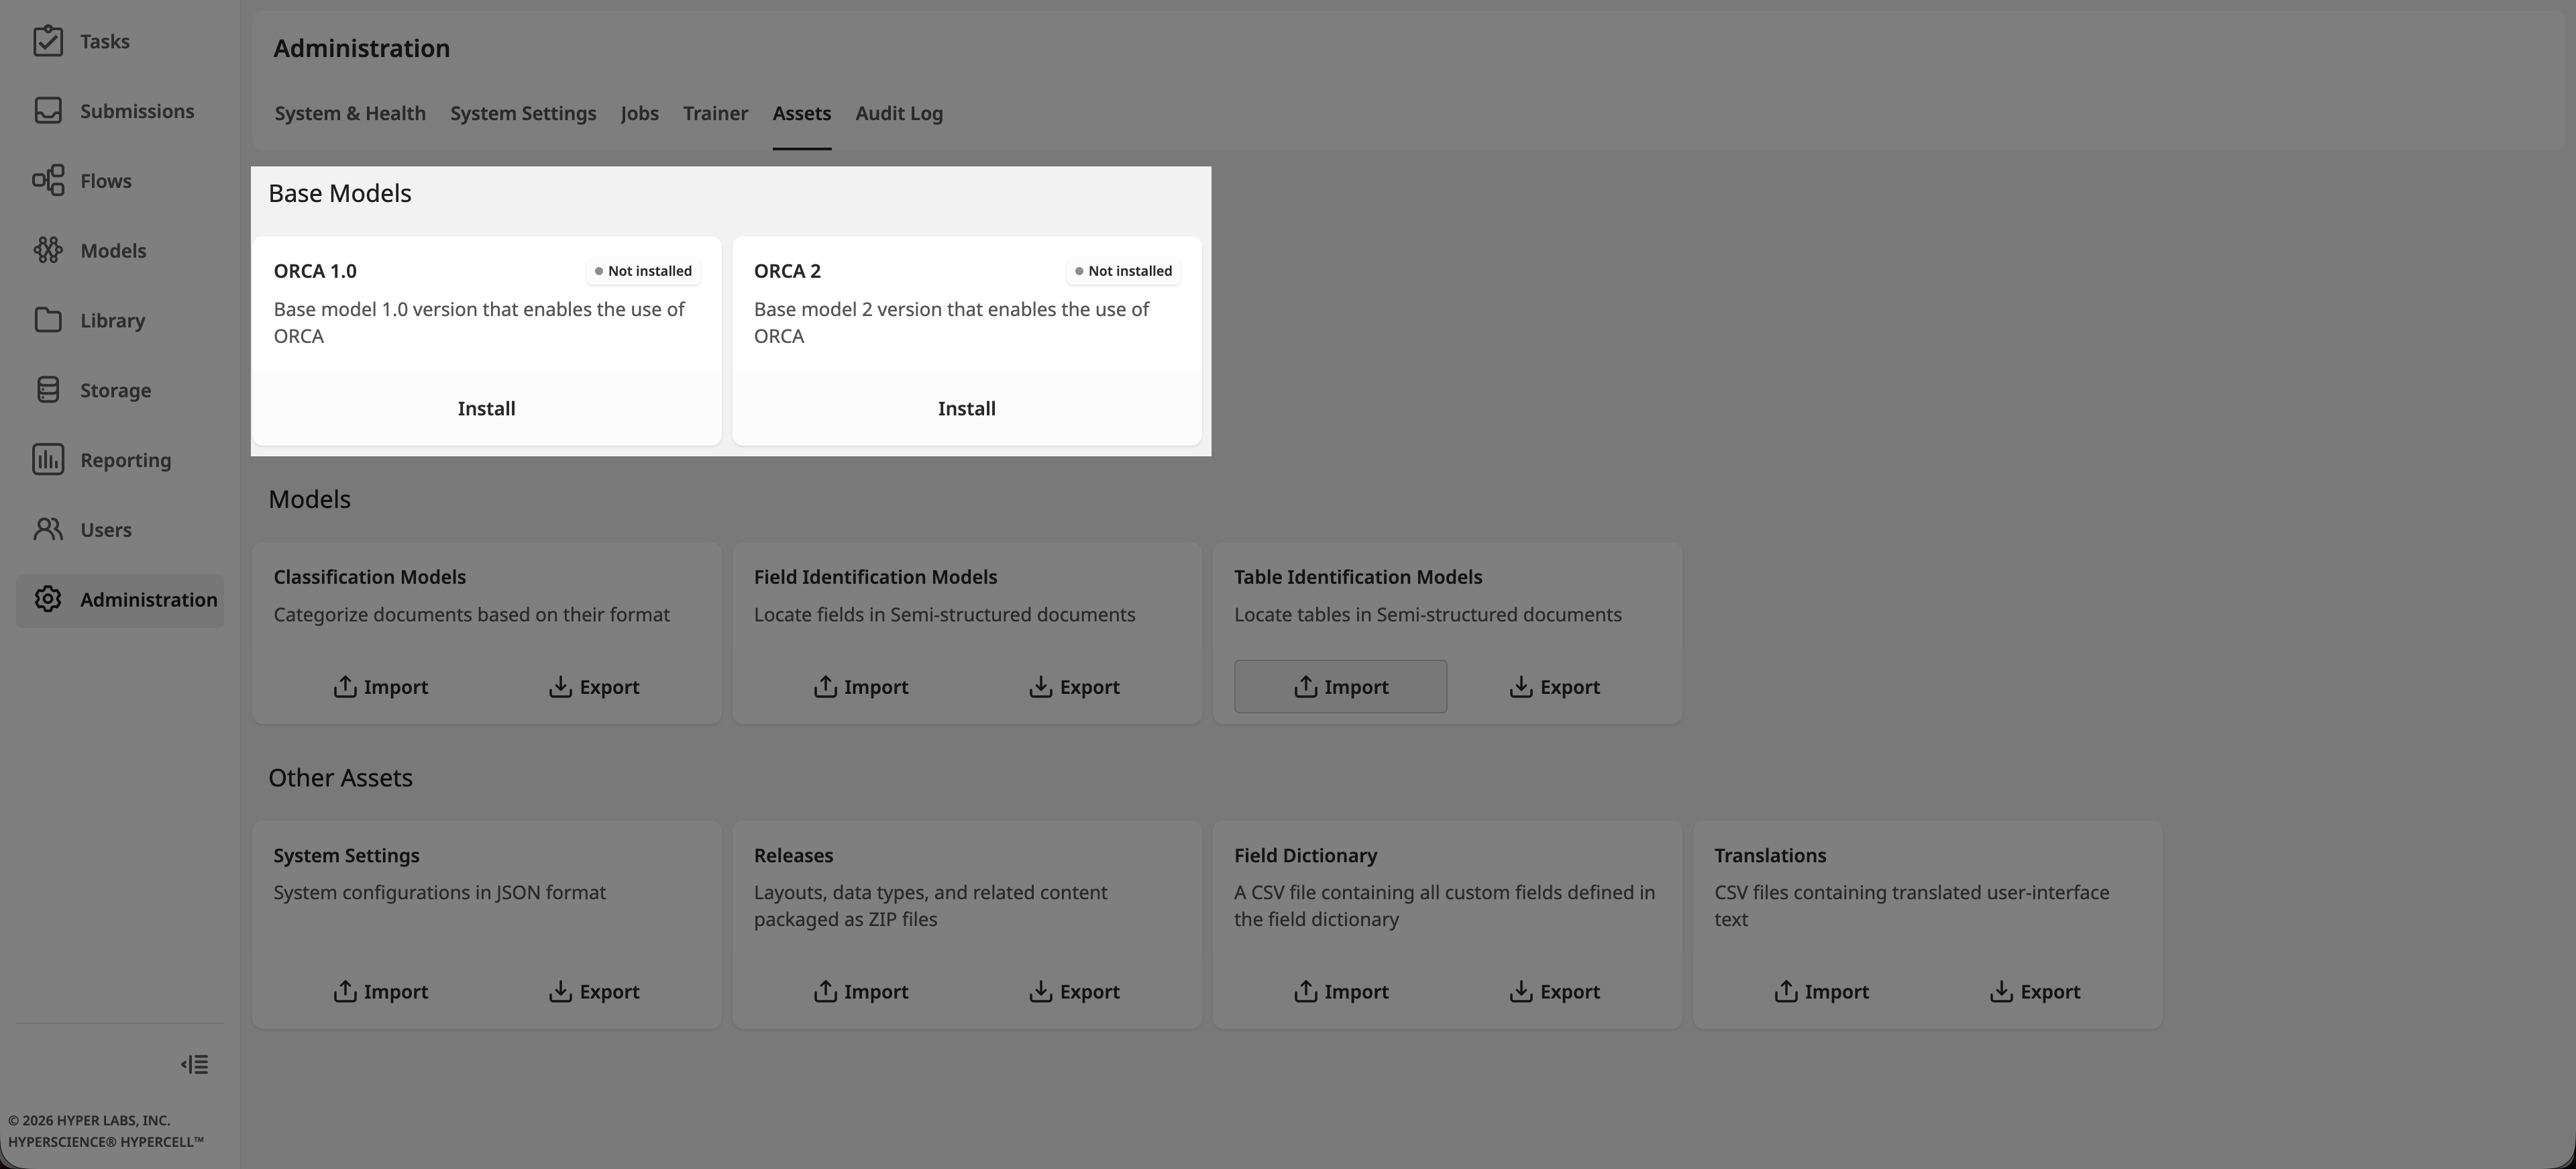
In deployments with internet access (e.g., SaaS deployments and non-air-gapped on-premise deployments), available ORCA base models appear as separate cards in Administration > Assets. They can be installed through a pre-configured artifact repository, Cloudsmith, or Hyperscience Package Registry.
ORCA 2 base model
In v43.2 and later, the ORCA 2 base model is available in addition to ORCA 1.0. Different base models provide different capabilities, and a specialized model inherits the capabilities of the base model selected for its training run. To learn more, see TDM for ORCA VLMs and Training a Specialized Model.
Installing multiple base models
In v43.2 and later, multiple ORCA base models can be installed on the same instance. Install one base model at a time. When one installation finishes, you can repeat the procedure for another available base model.
Follow the steps below to install a base model.
Go to Administration > Assets.
On the card for the ORCA base model you want to install, click Install.
Choose how the ORCA base model should be downloaded:
Fetch via Artifact Repository — Uses the pre-configured repository to download the base model.
Fetch via Cloudsmith — Downloads the base model using your Cloudsmith key. If you don’t have a key for your account, file a ticket on our Support portal.
Fetch via Hyperscience Package Registry — Downloads the base model from Hyperscience Package Registry.

Click Start.
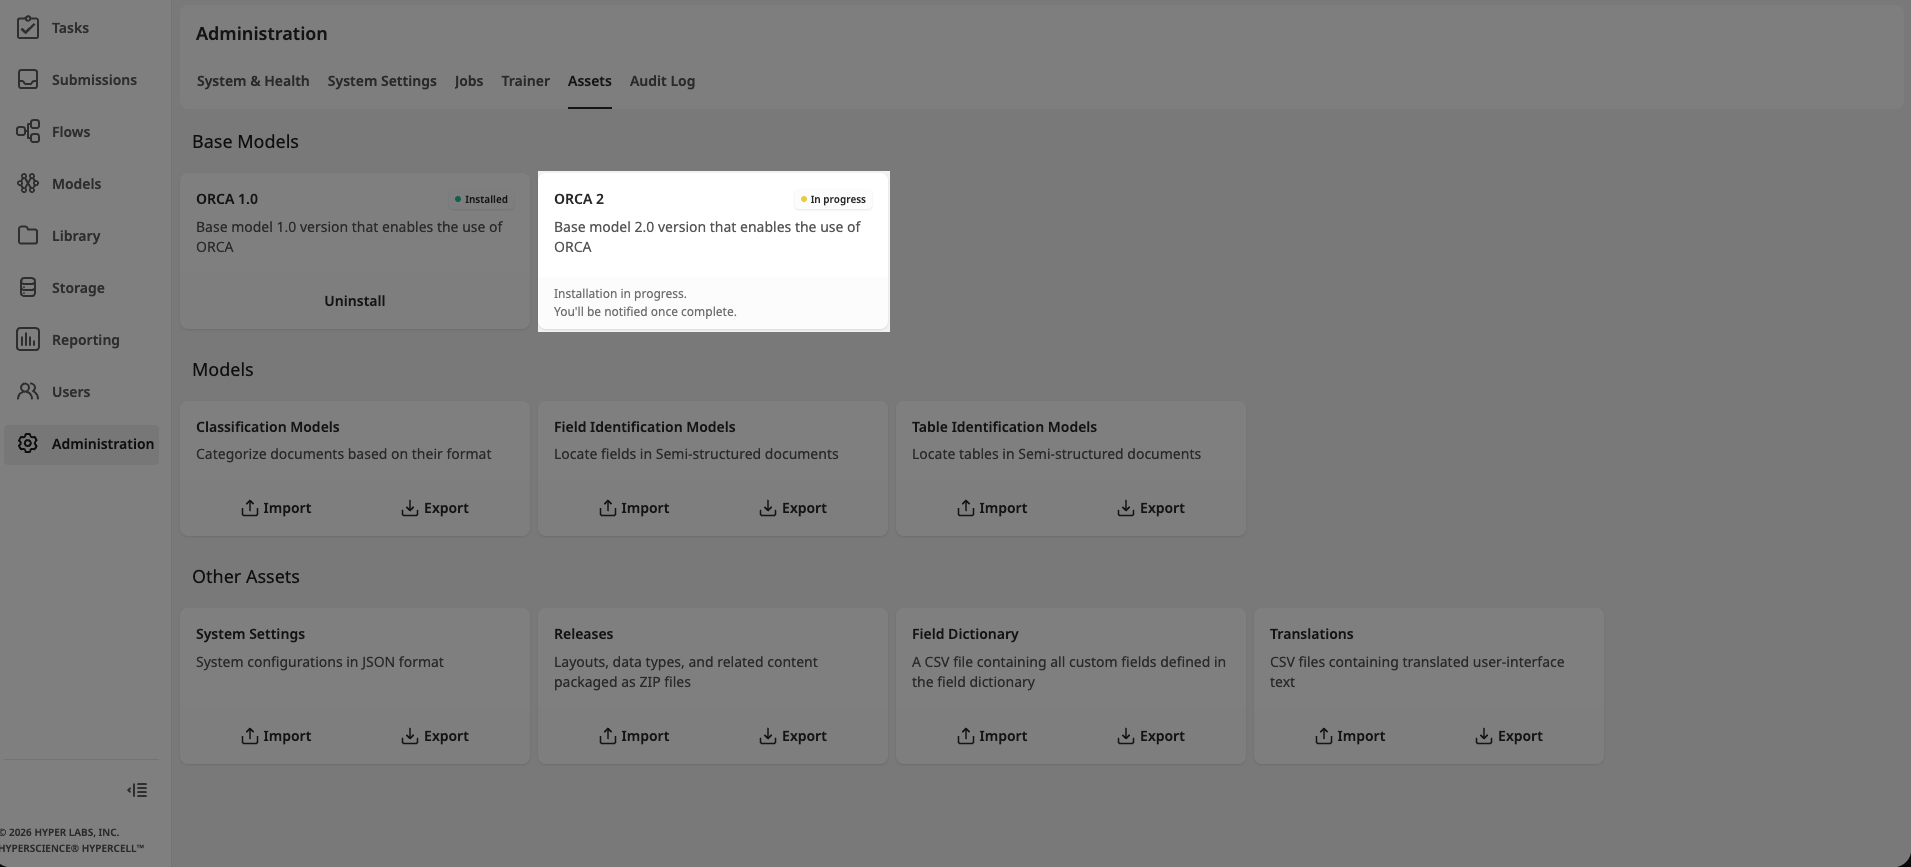
The selected ORCA base model card indicates that installation is in progress.
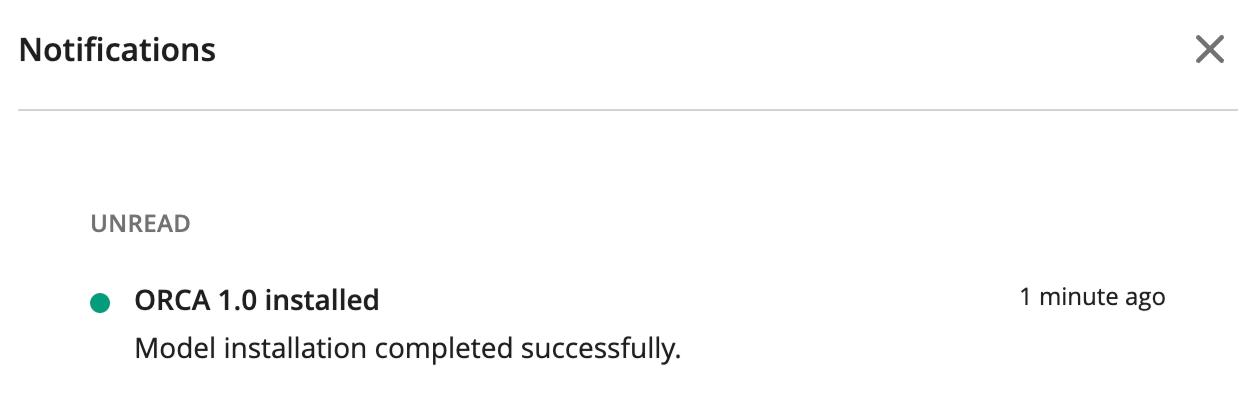
You’ll receive a notification in the notifications panel (
 ) once installation is complete.
Base model dependencies
Keep a base model installed while specialized models depend on it. If a required base model is not installed, the affected Model Definition and specialized model versions are unavailable for deployment. The History tab identifies the missing base model and provides an Install action. Learn more in Model Definitions.
Each installation runs in the background. When it is complete, the selected base model becomes available for document processing and specialized model training.
Installing an ORCA base model in air-gapped instances
In some on-premise deployments, the instance may be air-gapped, meaning it does not have direct internet access and cannot download assets from external repositories such as Cloudsmith.
In these cases, each ORCA base model must be installed through a manual transfer process. Repeat the process for every base model you want to install. Instead of downloading the model directly on your instance, you will:
Download the ORCA base model assets on a machine with internet access.
Transfer the files to your secured internal storage (e.g., S3).
Configure an Artifacts Repository pointing to that storage.
Install the ORCA base model from the configured repository.
Important considerations
This process is required only for air-gapped or restricted instances.
ORCA model assets are split into multiple chunks to improve reliability in restricted or unstable network conditions:
Each chunk can be downloaded independently.
If a download fails, only the affected chunk needs to be retried. This setup eliminates the need to restart the entire download process.
Downloads and uploads can be performed in parallel (e.g., uploading one chunk while others are still downloading), improving overall transfer efficiency.
Chunked downloads also help mitigate firewall timeouts and bandwidth limitations.
Each step is described in the sections below:
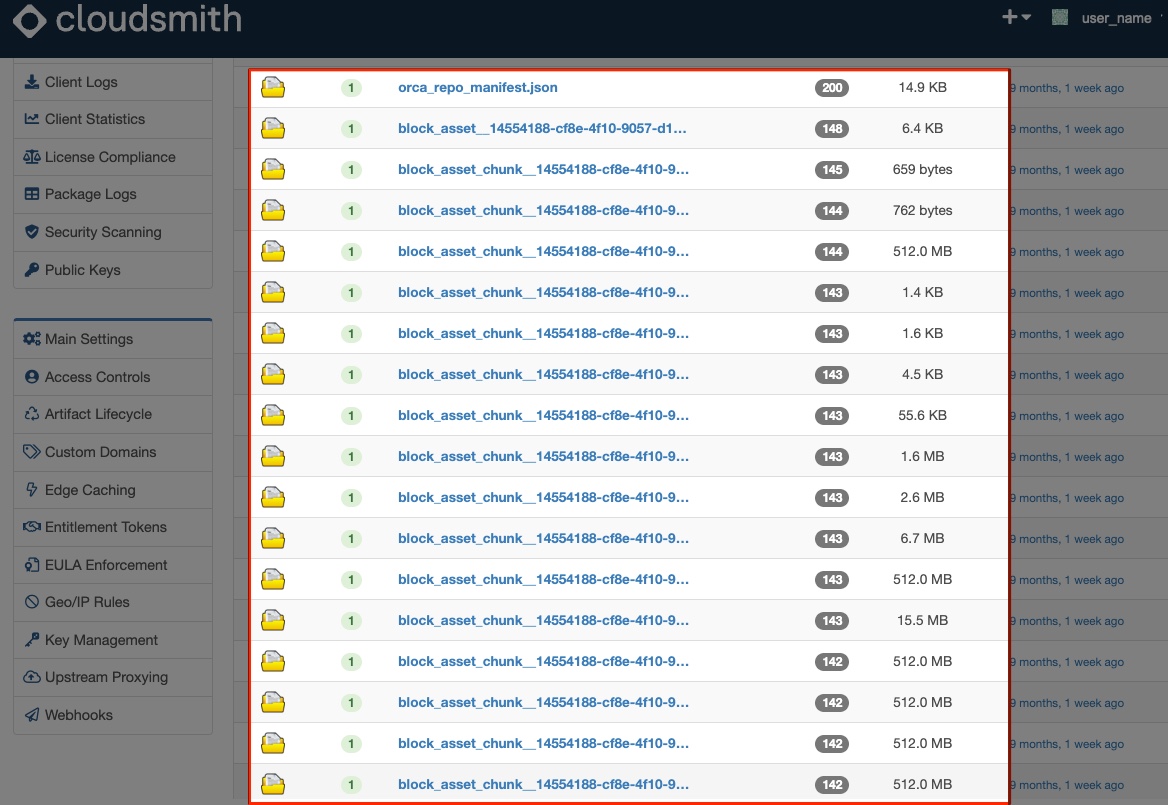
Download the selected ORCA base model's assets from Cloudsmith:
ORCA VLM assets are split into multiple files (chunks).
You need to download all required files before proceeding.
You can either download them manually or use a script to retrieve all required assets automatically:
All chunk files are listed in the selected base model's manifest.
The corresponding block-asset definition file.
The selected base model's manifest file. See the table below.
Each base model has its own manifest file
Use the name for the base model you are installing:
Base model | Manifest file |
|---|---|
ORCA 1.0 |
|
ORCA 2 (v43.2 and later) |
|
For any other base model, contact your Hyperscience representative for its manifest file name.
Automatically download ORCA VLM assets
You can download the files manually from the Cloudsmith repository. However, because the assets are split into multiple files, we recommend using a script to download them automatically.
Download ORCA VLM assets using a script:
The script downloads all required files directly from the Cloudsmith repository using your access key. It works as follows:
First, it downloads the manifest file set in
MANIFEST.This file contains the list of all required ORCA assets and their locations.
The script then uses this list to download all remaining files.
The example below is designed for instances that support bash (e.g., Linux or macOS).
For Windows instances, you may need to adapt the script (e.g., using PowerShell) or use a compatible shell. For more information, file a ticket on our Support portal.
Before running the script
Ensure you are using a valid Cloudsmith key with access to the
hs-assetsrepository.Ensure
curlandjqare installedSet
MANIFESTto the manifest file name for the base model you are installing.
KEY="your-cloudsmith-key"
MANIFEST="orca_repo_manifest.json"   # manifest file for the base model you are installing
BASE="https://dl.cloudsmith.io/${KEY}/hyperscience/hs-assets/raw/files"
OUT="./orca_chunks"
mkdir -p "$OUT"

# 1. Download the manifest (query params needed only here)
curl -o "${OUT}/${MANIFEST}" "${BASE}/${MANIFEST}?accept=true&accept_eula=1"

# 2. Download every chunk (NO query params — urljoin drops them, Cloudsmith doesn't need them)
jq -r '.artifacts[].location' "${OUT}/${MANIFEST}" | while read loc; do
  echo "Downloading ${loc} ..."
  curl -o "${OUT}/${loc}" "${BASE}/${loc}"
done
Prepare ORCA VLM assets for S3 repositories
S3 bucket with ZIP artifacts
This step is required only when using an S3 bucket with ZIPs artifact repository. It is not required when installing ORCA directly from Cloudsmith.
Before uploading the downloaded ORCA VLM assets to an S3 bucket, you must prepare them for use with the S3 bucket with ZIPs artifact repository type.
The downloaded ORCA package contains:
Chunk files (
block_asset_chunk__*.zip)A block asset definition file (
block_asset__*.json)The base model's manifest file (for example,
orca_repo_manifest.jsonfor ORCA 1.0)
To make the assets compatible with the artifact repository, run the provided Python script. The script creates ZIP bundles containing both the artifact and the corresponding manifest information required by the repository.
Before running the script, ensure that:
Python 3 is installed on the machine.
The downloaded ORCA assets and the manifest file are stored in the same directory.
The
wrap_artifacts_for_s3_zips.pyscript is available on the machine.
Save the following script as
wrap_artifacts_for_s3_zips.py:
"""Prepare downloaded ORCA VLM assets for an S3 bucket with ZIPs artifact repository.

Reads the manifest downloaded with an ORCA base model and writes one ZIP per
artifact. Each ZIP holds the artifact and a single-entry manifest named
repo_manifest.json, the only manifest name the application recognizes inside a ZIP.
"""
import argparse
import json
import logging
import zipfile
from pathlib import Path

logger = logging.getLogger(__name__)

# Name of the manifest inside each generated ZIP. The application recognizes a ZIP
# in the repository only if it contains a file with exactly this name.
ZIP_MANIFEST_NAME = 'repo_manifest.json'

# Name of the manifest downloaded with the ORCA 1.0 base model.
# For other base models, pass the downloaded manifest's name with --manifest.
DEFAULT_SOURCE_MANIFEST = 'orca_repo_manifest.json'


def wrap_artifacts(input_dir: Path, output_dir: Path, source_manifest: str) -> None:
    if output_dir.resolve() == input_dir.resolve():
        raise ValueError('--output must be a different directory from --input')

    manifest_path = input_dir / source_manifest
    if not manifest_path.is_file():
        raise FileNotFoundError(f'{manifest_path} not found')

    with manifest_path.open('r', encoding='utf-8') as f:
        manifest = json.load(f)

    artifacts = manifest.get('artifacts', [])
    if not artifacts:
        raise ValueError(f'No artifacts found in {manifest_path}')

    output_dir.mkdir(parents=True, exist_ok=True)

    for entry in artifacts:
        location = entry['location']
        source_file = input_dir / location
        if not source_file.is_file():
            raise FileNotFoundError(f'Artifact file missing: {source_file}')

        # Single-entry manifest for this wrapper ZIP
        single_manifest = {'artifacts': [entry]}
        single_manifest_bytes = json.dumps(single_manifest, indent=2).encode('utf-8')

        # Output ZIP name: same stem as the artifact, always `.zip`
        wrapper_name = Path(location).stem + '.zip'
        wrapper_path = output_dir / wrapper_name

        logger.info('Creating %s wrapping %s', wrapper_path.name, location)
        with zipfile.ZipFile(wrapper_path, mode='w', compression=zipfile.ZIP_STORED) as zf:
            zf.writestr(ZIP_MANIFEST_NAME, single_manifest_bytes)
            zf.write(source_file, arcname=location)

    logger.info('Wrote %d wrapper ZIPs to %s', len(artifacts), output_dir)


def main() -> None:
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument(
        '--input', '-i', required=True, type=Path,
        help='Directory containing the downloaded manifest and the artifact files',
    )
    parser.add_argument(
        '--output', '-o', required=True, type=Path,
        help='Directory where wrapper ZIPs will be written',
    )
    parser.add_argument(
        '--manifest', '-m', default=DEFAULT_SOURCE_MANIFEST,
        help='File name of the downloaded manifest in the input directory '
             '(default: %(default)s, the ORCA 1.0 manifest)',
    )
    args = parser.parse_args()

    logging.basicConfig(
        level=logging.INFO,
        format='%(asctime)s %(levelname)s %(message)s',
    )

    wrap_artifacts(args.input.expanduser(), args.output.expanduser(), args.manifest)


if __name__ == '__main__':
    main()
Run the script. For ORCA 1.0:
python3 wrap_artifacts_for_s3_zips.py --input ./orca_chunks --output ./orca_zipsFor other base models, add
--manifestwith the base model's manifest file name. For example, for ORCA 2 (v43.2 and later):
python3 wrap_artifacts_for_s3_zips.py --input ./orca_chunks --output ./orca_2_zips --manifest orca_2_repo_manifest.jsonWhere:
--inputspecifies the directory containing the downloaded ORCA assets and the manifest file.--outputspecifies the directory where the generated ZIP bundles will be created. It must be a different directory from--input.--manifestspecifies the file name of the downloaded manifest. Omit it for ORCA 1.0.
The script creates a ZIP file for each ORCA artifact. These generated ZIP files must be uploaded to your S3 bucket and used when configuring the artifact repository.
Upload the prepared ORCA VLM assets to internal storage (S3):
Go to your S3 bucket (e.g.,
s3://hs-build-artifact/block-asset/).Create a folder for the base model, for example,
orcafor ORCA 1.0 ororca_2for ORCA 2. A separate folder for each base model makes it easier to remove one model's files later.Final path for ORCA 1.0:
s3://hs-build-artifact/block-asset/orca/
Place the generated ZIP files in the folder.
Configure the Artifact Repository in your instance:
Add
/adminat the end of your instance’s URL:instance.hs.ai/admin
Using the browser’s search, find
Artifact repositorys.Click Add Artifacts Repository.
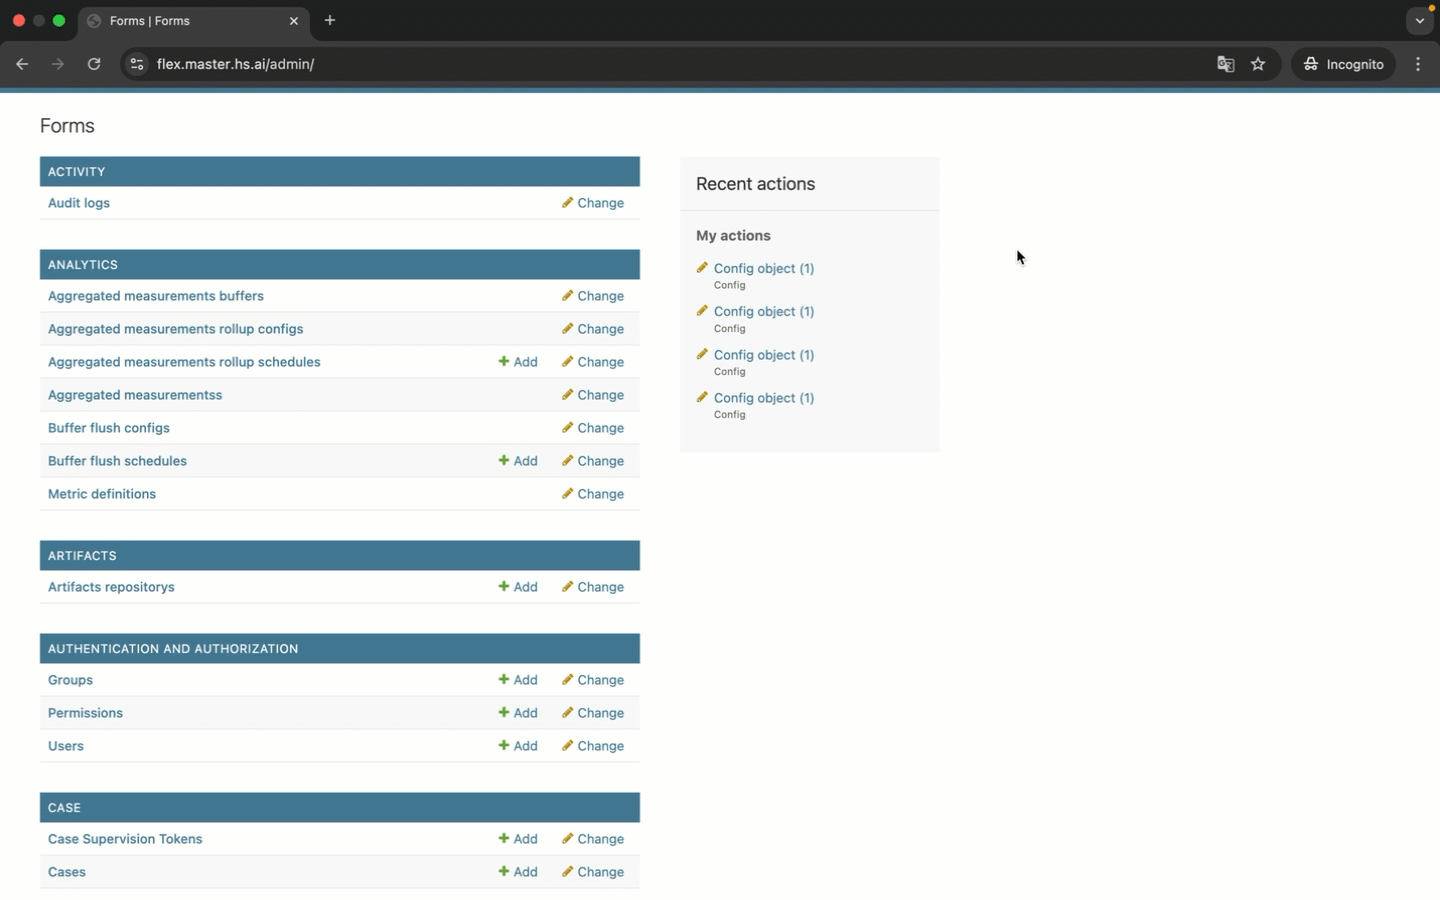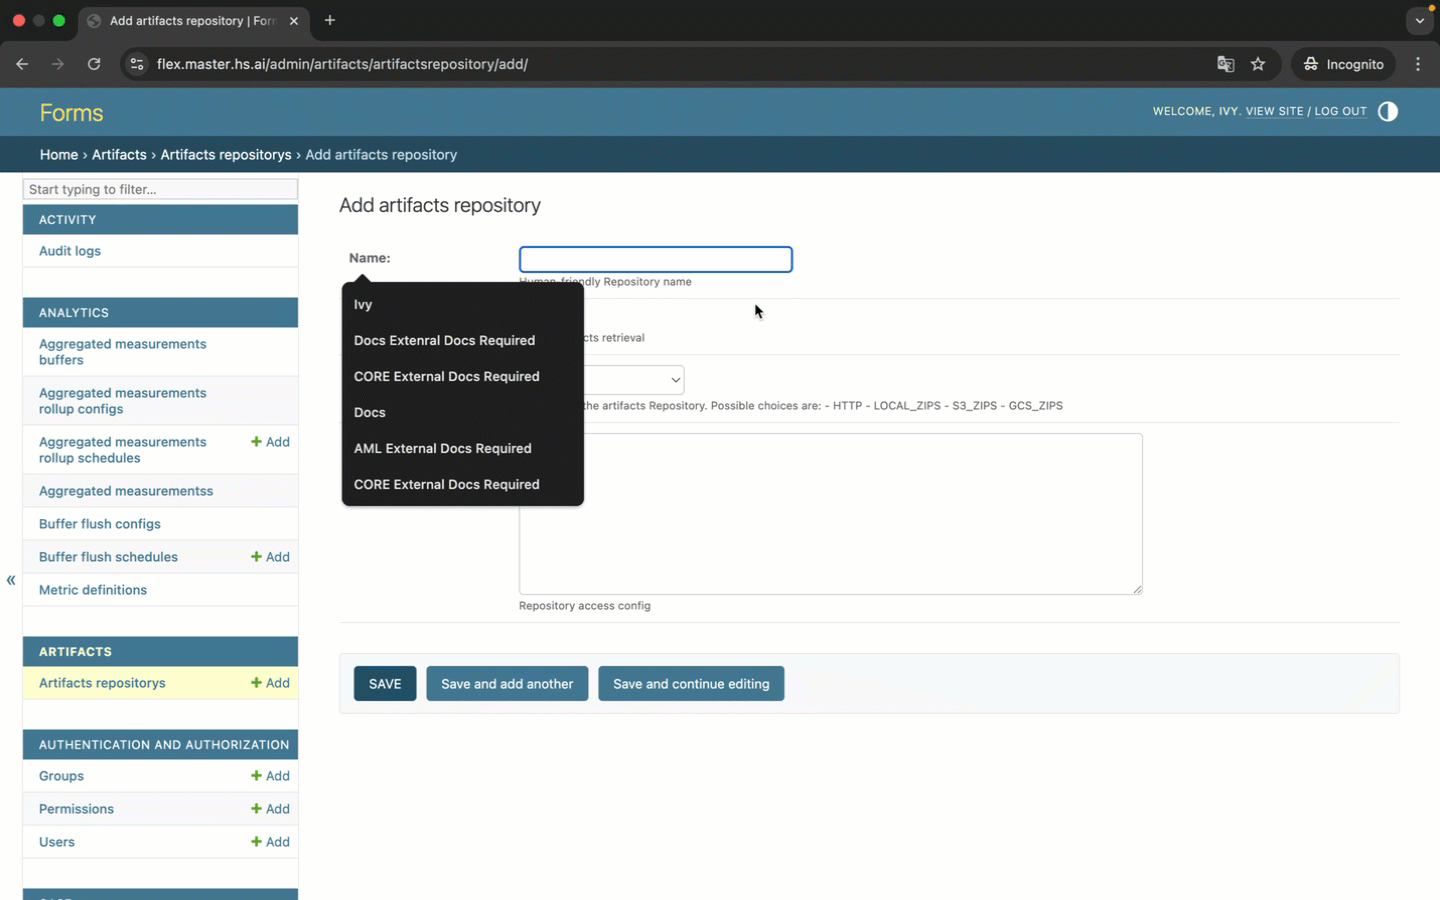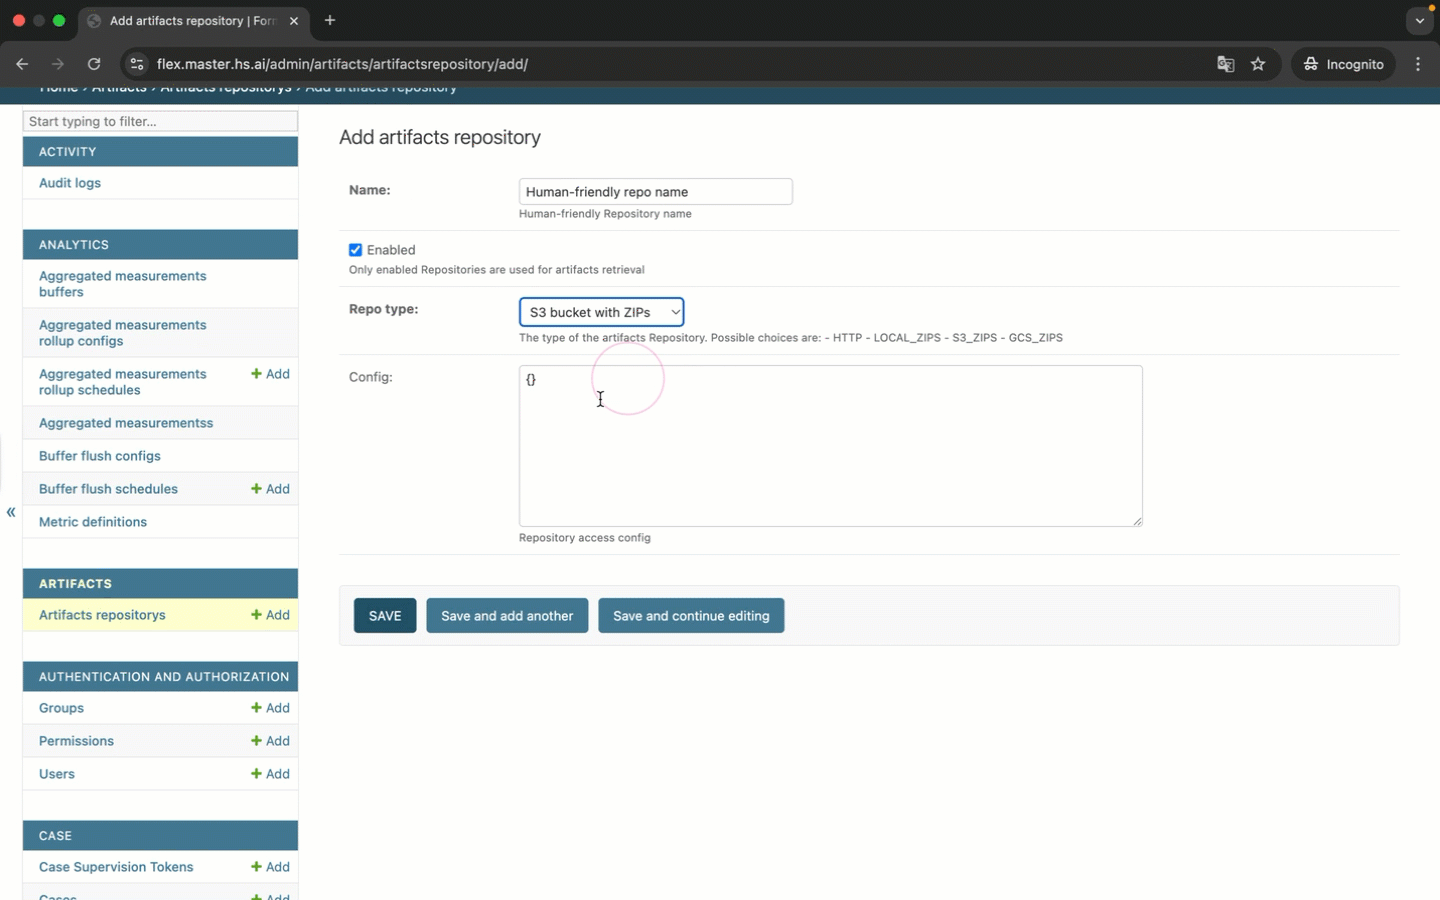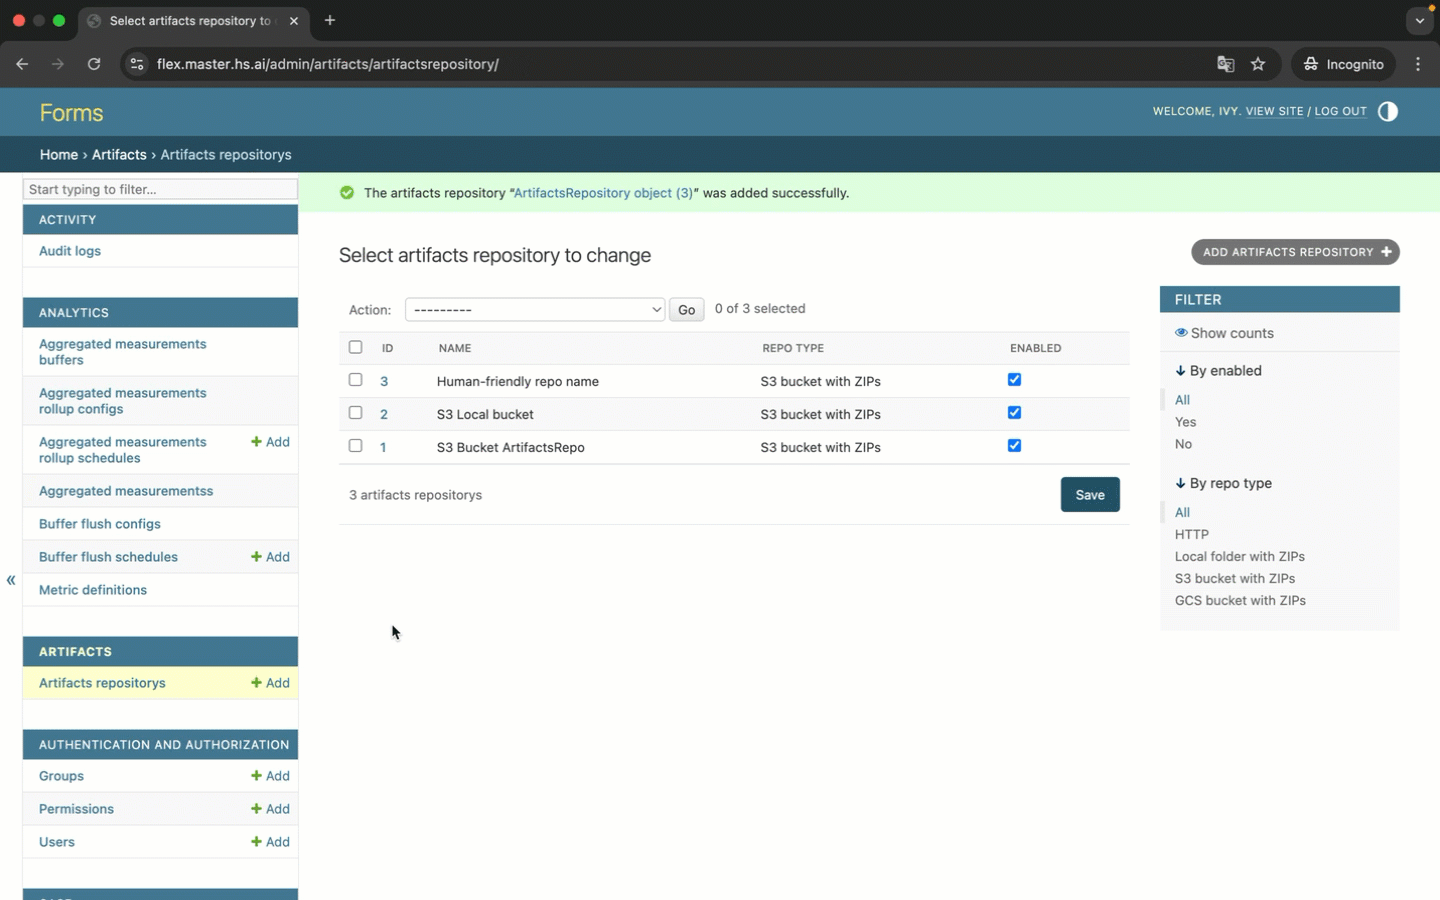
Enter a name for the repository.
We recommend choosing a human-friendly repository name, for example, S3.
From the Repo type drop-down list, select S3 bucket with ZIPs.
Enter the following in the Configs field:
{
  "s3_path": "s3://hs-build-artifact/block-asset/",
  "s3_region": null
}
The repository reads ZIP files in every folder under s3_path, so one repository covers all the base models you upload.
Go to Administration > Assets.
On the card for the ORCA base model whose assets you transferred, click Install.
Choose Fetch via Artifact Repository. The system will now install the ORCA base model using the files from your internal storage.
Generated ZIP bundles
The generated ZIP bundles replace the originally downloaded files for S3 uploads.
Next steps
After installing an ORCA base model, complete the following steps to use VLM Field Extraction:
Create or update a Semi-structured layout with at least one field. See Creating Semi-structured Layouts.
Include the layout in a release, and configure the ORCA subflow in the Document Processing flow. See Document Processing Flow.
Optional: To adapt the base model to your specific use case, create a model definition and train a specialized model.